You ran a crawl, or a client asked you about it, and now you're staring at a list of URLs that go nowhere. Some of them look like they came out of an AI writing tool or an AI-assisted content workflow: plausible slugs, a folder structure that almost matches your site, but no actual page behind them. The question in front of you isn't really "did AI cause this." It's "what do I do with each one." This piece walks through that decision so you can look at any broken or invented URL and know within a few minutes whether it needs a redirect, a real 404, or nothing at all.
The short answer: where the URL came from doesn't decide what happens to it. An AI-hallucinated link is just a broken link with an unusual origin story, and it gets sorted the same way any broken link does. Redirect it only when there's a real page it should point to. If there isn't one, let it 404 and move the fix upstream to wherever the bad link is coming from. Underneath the question "should i redirect hallucinated links," what you're really deciding is whether a real destination exists, and everything below is built around answering that.
The URL never pointed to anything real
This is the most common shape a broken links from AI content problem takes, and it's the one agencies get wrong most often, usually by over-fixing it.
What it looks like: the crawler flags a URL with a path that sounds right for your site, maybe /blog/how-to-scale-content-2024 or /guides/api-migration-checklist, but you never published anything at that address. It wasn't renamed, moved, or retired. It simply never existed. An AI drafting tool invented it as a plausible-sounding citation or internal reference, and it got published as a link without anyone checking where it actually led.
How to confirm it: pull up your CMS content inventory, your sitemap files, and your deployment history and search for the slug. Check your internal-link report to see where the bad link is coming from. If you have server logs or analytics, look at whether real visitors are requesting the URL or whether it's only bots and crawlers finding it. A URL with no historical page, no plausible intended destination, and no meaningful source of real traffic is a strong match for this branch.
Fix: go to the page that contains the bad link and remove it, or correct it to point somewhere real. Let the URL itself keep returning a genuine 404 or 410. Do not redirect it to your homepage, your blog index, or the nearest article that shares a keyword. A nonexistent page doesn't gain any value because an AI system generated the link to it, and redirecting it implies the page moved, which isn't true. Most bad advice about ai generated fake urls seo comes from skipping this step and redirecting on reflex instead of checking whether a real destination exists.
The URL is a typo for a page you already have
What it looks like: the broken link is close enough to a real URL that the intent is obvious. A missing hyphen, a wrong plural, an old slug format, a swapped word order. Someone (or something) meant to link to a page you actually have, and got the address slightly wrong.
How to confirm it: compare the broken URL against your current site inventory and read the anchor text and surrounding sentence on the page that links to it. There should be exactly one existing page that clearly satisfies what the link is trying to point to. Don't stretch this: "roughly the same topic" isn't the same as "obviously the same intended page." If you're guessing, you're in the wrong branch.
Fix: correct the link at its source first. That matters more than the redirect itself, since a fixed source link means future crawls won't even trip over the problem again. Then, if the old or malformed URL might still get requested by users, other crawlers, or outside sites that already linked to it, add a relevant permanent redirect (301 or 308) to the correct page. The redirect is a safety net, not a substitute for fixing the link that caused the problem.
The URL returns a 200, but there's nothing there
What it looks like: you request the broken URL and instead of a 404, you get a "sorry, page not found" message wrapped in your site's normal template, with a 200 OK server response underneath it. This usually comes from a catch-all route or an unfinished CMS template rather than anything AI did directly, but it's exactly the kind of thing that lets an AI-hallucinated link hide in plain sight, since it looks like a working page until you check the actual status code.
How to confirm it: don't trust what the page says on screen. Check the real HTTP response in a crawler, in your browser's developer tools, from the command line, or through Google's URL Inspection tool. If the page visually says "not found" but the server reports success, that's a soft 404, and it behaves differently from a real one in how search engines treat it.
Fix: pick the outcome that's actually true. If there's real content at that URL, it should return 200 and stay that way. If the content moved somewhere with a genuine replacement, redirect to it. If the URL doesn't correspond to anything, fix the response so it returns a proper 404 or 410 instead of a disguised 200. A soft 404 can waste crawl attention on a page that isn't unique or useful, and it leaves visitors confused about whether they found something or not.
The page used to exist and moved somewhere else
What it looks like: unlike the first branch, this one has real history. The URL served an actual page at some point, or your team deliberately replaced it with a new address as part of a rename, a CMS migration, or a content consolidation. An AI-assisted workflow can still be involved here, usually by generating a link to the old slug instead of the current one.
How to confirm it: check your CMS history, past publication records, any redirects you already have configured, and your URL mapping if you kept one during a migration. Compare the old and new content side by side. The bar is whether the new page is a genuine successor to the old one, not just something convenient to point at.
Fix: set up a permanent redirect (301 or 308) from the old URL to the new one, then update your internal links, canonical tags, and sitemap to reference the new URL directly instead of relying on the redirect to carry the weight forever. If several old pages were consolidated into one new page, redirecting all of them to that single destination is appropriate, as long as the consolidation is real and the new page actually covers what the old ones did.
The page is gone, and nothing replaced it
What it looks like: the content was intentionally retired. A product got discontinued, a service page got pulled, an old campaign page ran its course. There's no successor page that does the same job, and pretending otherwise with a redirect would be the wrong move.
How to confirm it: ask whoever owns that content area whether anything was meant to replace the page. If a visitor landed on a proposed destination, would they honestly recognize it as the same thing they were looking for? If the answer is no, this branch is the right one, even if it means leaving a 404 in your crawl report.
Fix: return a proper 404 or 410. Fixing a broken links from AI content issue doesn't mean eliminating every 404 you can see; some 404s are simply correct. A 410 can signal more clearly that the removal was deliberate, though for search purposes the two are treated the same, so don't pick one over the other expecting a ranking difference. A custom error page can still offer useful navigation to visitors, as long as the server keeps returning the real 404 or 410 status underneath it.
The URL only shows up in someone else's AI answer, not on your own site
What it looks like: the broken URL isn't linked anywhere on your site at all. It exists because an AI chatbot, an AI answer, or a third-party article mentioned it, and someone followed the fake citation straight to your domain, where of course nothing is there.
How to confirm it: separate where the URL was discovered from where it's actually linked. Check Search Console, your backlink data, analytics, and a full site crawl to see whether the URL appears anywhere in your own navigation, content, or sitemap. If it doesn't, the problem lives outside your site.
Fix: in most cases, there's nothing to fix. You can't repair a URL that exists only in an AI system's output or a third party's article. If real requests are reaching your server for it, return a proper 404 or 410 like you would for any other nonexistent page. Only dig further if the volume is unusual, the traffic pattern looks like abuse, or it's exposing something you'd rather not have exposed, like an internal path structure. This is the branch where agencies waste the most time trying to "fix" something that was never under their control.
None of these matched
If you've worked through the branches above and the broken URL still doesn't fit cleanly, step back and check two things before deciding anything. First, confirm the URL is actually broken and not a page that should exist but is failing for a technical reason (permissions, deployment, routing), since that calls for restoring the page rather than redirecting or letting it 404. Second, check whether the page is simply orphaned: it exists and works, but nothing on your site links to it, so a crawler or an AI-assisted tool can't find a path to it and may be inventing one instead. An orphan page needs a real internal link pointing to it, not a redirect rule.
If the URL genuinely fits none of the branches, treat it conservatively: don't redirect on a guess, and don't leave an internal link pointing at something broken while you figure it out. Pull the link, let the URL 404, and revisit once you have more information.
Getting from diagnosis to a fix you can trust
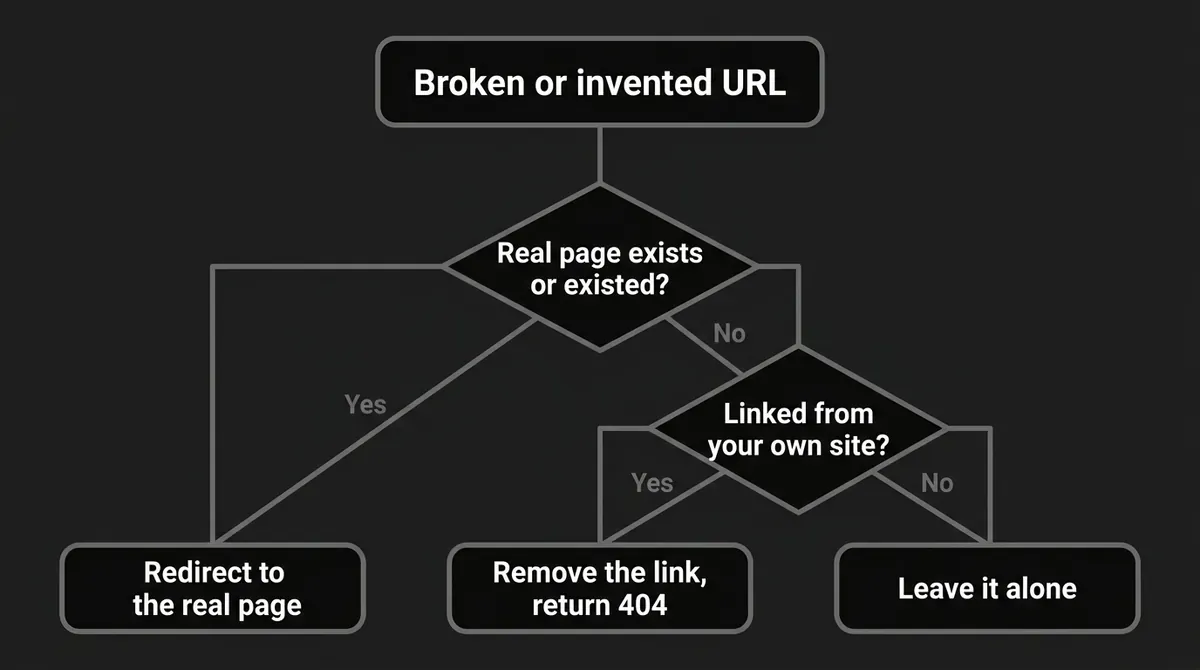
Once you've sorted a batch of AI hallucinated links into these categories, fixing ai invented links is mostly mechanical work: fix the source links first, add redirects only where a real destination earns them, and let the rest return honest 404s. Keep a simple record as you go: the broken URL, which branch it fell into, what you did about it, and who owns the fix, so the next audit doesn't start from zero.
The bigger pattern worth noticing is where these links keep coming from. If a content workflow keeps generating plausible-but-fake URLs, that's worth tracing back to the drafting or review step rather than treating each broken link as a one-off cleanup task. Agencies running content across several client sites tend to hit this at scale, since one workflow issue can show up as broken links on every account at once. A platform like DeepSmith that keeps content production and on-brand review in one place can make that kind of pattern easier to catch before a draft goes live, rather than after a crawl turns up a list of dead links. If that's the recurring problem, you can try DeepSmith free for seven days and see whether it catches the pattern before the next crawl does.
If the volume is small, a spreadsheet and an afternoon will get you through it. If it's recurring across many pages or many client sites, it's worth escalating to whoever owns the content workflow, since the redirect decisions above only clean up the symptom.