

If you are trying to figure out how to build a marketing chatbot, the hardest part is not picking a vendor. It is deciding what the bot is actually for, scoping it to one job it can do well, and building the guardrails that keep it from making promises it cannot keep. This guide walks through that process, from the pitch you take to leadership to the week after launch when you are reading transcripts and fixing what broke. By the end you will have a project plan to build a chatbot marketing and sales can both stand behind, not just a list of platform features.
This is not a chatbot platform comparison. Picking a vendor matters less than what you decide before you open a builder, so what follows is the chatbot launch process itself, in the order most teams actually run it.
Step 1: Pitch one measurable outcome
Start with the business problem, not the technology. Before you write a single conversation flow, you need to answer five questions: who will use the bot, what situation brings them to it, what job it should complete, what business result should move, and what it will explicitly not do.
Pick one primary outcome for the first release. That might be more qualified demo requests, faster answers to the pre-sales questions your team answers over and over, help choosing between plans, or routing complex questions to the right person faster. A marketing chatbot can eventually support several goals, but the first version needs one number everyone agrees to watch. Everything else, like answer quality or handoff rate, is a metric that protects the experience rather than the one that proves it worked.
Write this down as a one-page charter: working name, target audience and traffic source, the primary use case, a business owner, a customer owner (marketing, sales, or support), which pages or channels the bot will appear on, approved data sources, the systems it needs to read or update, who handles human handoff, the primary KPI, a launch window, and what is explicitly out of scope. This document keeps a chatbot project from drifting into "answer everything," the fastest way to make a first release unmanageable.
When you rank candidate use cases, weigh customer value, business value, how often the issue comes up, whether the desired outcome fits in one sentence, whether the answers and source documents already exist, whether the integrations you need are available, what happens if the bot gets it wrong, whether a person can take over cleanly, and whether you can measure the outcome end to end. Good first candidates include product selection, quote assistance, demo qualification, appointment booking, and routing visitors to the right resource: contained, well understood, and forgiving if the bot needs to hand off.
Pro tip: don't promise a percentage improvement before you have measured the current journey. Set a target only after you know the denominator, the measurement window, and the traffic source you're comparing against. If no baseline exists yet, say so and plan to start measuring at launch instead of inventing a number to put in the deck.
DeepSmith is not a chatbot builder and it will not run the conversation your visitors have. Its role here is upstream: its AI visibility metrics can help you see which questions buyers are already asking AI engines about your category, which is useful evidence when you're picking that one outcome. Keep that distinction in mind, because the chatbot itself is a separate system with separate KPIs.
Step 2: Choose and scope the first customer journey
Map the journey from the point someone starts the conversation to the outcome you defined in step one. Don't guess at how customers phrase what they need. Pull the real evidence: live chat transcripts, sales call notes, support tickets, the search queries hitting your site, contact form submissions, pricing questions, and the questions your sales team keeps answering by hand. A workflow for mining support and sales calls for the language customers actually use works just as well for chatbot scoping as it does for content planning, since both start from the same first-party records.
For the journey you're building, write down the entry condition (why someone starts this conversation), the user's goal, what information the bot needs to know, the questions it has to ask to get there, what happens at each stage, the conversion or completion event, the conditions that require a person instead, what's out of scope, and what data gets stored or passed along. A typical marketing journey looks like this: a visitor asks which product fits them, the bot asks a couple of clarifying questions about company type or team size, it recommends an option from approved information, answers a follow-up question, then offers a demo or a human conversation and only asks for the contact details needed for that next step.
Before you write a single answer, sort every request into three lists. In scope is what the first release can answer or complete reliably. Deferred is useful but needs new content, a new integration, or a different approval process first. Out of scope is what the bot should decline, redirect, or send straight to a person. Treat that last category as a real, designed-for intent rather than an accidental failure: give it a helpful response and a next step, don't just let the bot flounder.
The scope is ready when every priority intent has a plain-language description, real customer phrasing to match against, a desired outcome, an approved response, the data fields it needs, a success event, a fallback path, and someone responsible for keeping the answer accurate.
Common mistake: treating a big pile of scraped pages as a finished scope. A knowledge base full of content doesn't tell you which questions the bot should answer, which actions it's allowed to take, or when it needs to stop and hand off. Those are separate decisions you still have to make.
DeepSmith's Content Map can help a marketing team see what content already exists and where the gaps are, which matters if the chatbot's journey depends on pages that don't exist yet or are thin. That's support for the content around the bot, not the bot's own runtime knowledge base.
Step 3: Turn customer language into conversation flows
Build your intent library from real conversations, not from how your team would phrase the question. Collect the short questions and the long ones, the synonyms, the typos, the requests phrased as problems instead of features, the messages that pack two questions into one, and the ones that are close to your scope but not quite in it. Then design the conversation as a series of explicit states instead of one open-ended prompt: for each state, know the bot's goal, what the user is likely trying to do, what's already known, the next question, what counts as a valid answer, the success event, and the recovery path if it goes sideways.
The opening message carries more weight than it seems like it should. It needs to say clearly what the bot is, what it can help with, and offer two or three concrete starting points, without ever claiming to be a person. "I can help you choose a plan, answer product questions, or set up a demo" tells the visitor exactly what to do next. "How can I help?" just makes them guess.
Fallback needs to feel like a conversation, not an error message. A working sequence looks like: notice the low-confidence input, acknowledge the uncertainty without blaming the user, offer a short interpretation or a small set of choices, ask them to confirm, and if they reject it, ask them to rephrase once more before falling back to a human route. Something like "I'm not sure whether you're asking about pricing, implementation, or a demo, which one should I help with?" does the job better than a generic "I didn't understand that."
Decide your handoff triggers before launch, not during it: the user asks for a person directly, the bot fails to understand after a set number of tries, the user sounds frustrated, the question needs private account information, the decision is high-risk, or an integration the bot depends on is down. When handoff happens, send the human team the transcript, the user's stated goal, whatever contact information was collected, the answers already given, and any unresolved question, and then stop the bot from responding. A customer getting two different answers from a bot and a person at the same time is worse than a slow handoff.
Writing FAQ-style answers your chatbot can draw from is close cousin work to writing FAQ sections pulled into AI answers: both reward a direct answer in the first sentence, sourced from real buyer language, with the qualification or limitation stated plainly rather than buried.
Step 4: Prepare the knowledge base and integrations
Keep the knowledge layer separate from the conversation logic. The knowledge layer answers "what is true," and the conversation layer decides "what should happen next." Build an inventory of approved sources: product pages, pricing, documentation, support articles, policies, implementation guides, and any comparison content you're comfortable exposing publicly. For each one, record an owner, the audience it's written for, the last review date, what product or region it covers, and when it expires or gets replaced. Drafts, internal strategy documents, private customer records, and anything that hasn't cleared product or legal review stay out.
If you're using retrieval to ground the bot's answers, the pattern is straightforward: the user asks a question, the system searches your approved sources for relevant passages, those passages get added to the model's prompt, and the model generates an answer grounded in them. It's worth understanding how AI systems retrieve and read pages before you build this layer, since the same retrieval-then-generate pattern that decides whether your content gets cited in AI search also decides whether your own chatbot answers correctly. Managed services such as Amazon Bedrock Knowledge Bases can handle much of the ingestion, indexing, and retrieval infrastructure, while a custom build means your own team owns those pieces. Retrieval improves access to current information, but it does not guarantee correctness. The bot can still pull the wrong passage, use something stale, or produce an answer nothing in your sources supports.
Set explicit grounding rules: answer only from approved sources for factual claims, say plainly when the sources don't support an answer instead of filling the gap with something plausible-sounding, prefer the newest approved version when sources conflict, and re-index whenever pricing or policy changes. Test retrieval with questions whose answers you already know, so you can tell when it's pulling the wrong thing.
Common integrations include CRM lead creation, calendar booking, marketing automation enrollment, and consent management. Before you promise any action inside the conversation, confirm the system you're connecting to has a supported API, an authentication method, and an owner. Every integration also needs a failure behavior: if calendar booking fails, the bot should say so and offer a callback, never claim a meeting was booked when it wasn't.
If your team is wiring up multiple data sources for the bot to draw on, the connection order matters. Connecting data sources in the right order, starting with the sources that carry the most weight and building out from there, is the same discipline that keeps a chatbot's knowledge layer from turning into an unmanaged pile of half-connected systems. If your team hasn't worked with this kind of connector before, a plain-language read on what these servers actually do is worth having before your engineers start wiring anything up.
Common mistake: measuring the knowledge base by size. A smaller set of sources that's actually maintained and accurate beats a large archive full of contradictions and outdated pricing.
Step 5: Build the response, lead capture, and handoff logic
Build the smallest useful version first: the widget shell, the opening message, the top intents and their happy paths, the retrieval connection, structured questions with validation, the primary conversion action, the CRM handoff, fallback and escalation, and analytics events, roughly in that order.
Use progressive qualification instead of a long form dropped into the chat window. Understand what the visitor wants, give them something useful right away, ask one relevant question at a time, explain briefly why you're asking, and only request contact details once there's a clear reason to continue. For every field you collect, know why it's needed, whether it's optional, where it's stored, and what happens if the person declines to give it.
Don't make marketing consent a hidden condition of getting a basic answer. If following up by email is optional, make it genuinely optional and record that preference separately from the operational request the visitor actually came for.
A good chatbot answer usually has four parts: the direct answer, any important qualification or limit, one clear next action, and an optional link if someone wants to go deeper. Skip the long paragraphs, the generic enthusiasm, and the multiple competing calls to action fighting for the visitor's attention.
Common mistake: letting the model decide on its own whether to take a sensitive or irreversible action from free text alone. Use structured tools with allowlisted operations, validate every argument before it executes, and require human approval anywhere the consequences are big enough to justify the extra step.
Step 6: Add privacy, security, and accessibility controls
The exact legal requirements depend on where your visitors are and what data you're collecting, so treat this as an implementation checklist rather than legal advice. For every way the chatbot processes data, identify the purpose, document the lawful basis before you start processing, and explain both in your privacy notice. Where you rely on consent, make it specific and given through a clear affirmative action, and make withdrawing it just as easy as giving it. Collect only what the current job needs, define retention and deletion rules, and restrict who can read transcripts. Guidance like the ICO's rules on lawfulness in AI is written for UK GDPR specifically, so treat it as a strong reference point rather than a universal standard, and check what applies in your own jurisdiction.
On the security side, threat-model the whole system, not just the prompt. Consider direct prompt injection from the user, indirect injection hiding in a retrieved document, system prompt leakage, and tool permissions that are broader than they need to be. The OWASP Top 10 for LLM applications is a useful checklist here: treat retrieved text as data rather than trusted instructions, keep secrets out of anything the user can see, use least-privilege credentials for every integration, and require confirmation before any consequential action fires.
Accessibility has to be built in from the start, not patched on as a floating widget bolted onto the page. A semantic markup audit covers some of the same underlying discipline: proper structure, clear labels, and content that holds together outside its original visual layout, all of which matter just as much for a chat interface as a page. Test keyboard access and visible focus, screen reader announcements when a new message arrives, readable contrast, timeout warnings with a way to recover, and tolerance for common typos. The MITRE Chatbot Accessibility Playbook is worth reading here too, since general web accessibility standards don't fully cover chatbot-specific patterns yet, which makes early testing with a diverse group of real users more important than checking a single standard off a list.
Pro tip: write a short "do not say or do" list for the bot. Cover unsupported claims, confidential information, regulated advice, competitor claims, unapproved discounts, and any action that needs a human or an authenticated system to complete.
Step 7: Test the chatbot against launch gates
Testing a chatbot means more than confirming the happy path works. Build a matrix that covers functional cases (every priority intent, missing information, typos, multi-intent messages, out-of-scope requests, explicit requests for a person), knowledge cases (correct source retrieval, conflicting sources, stale content, pricing accuracy, tone), integration cases (CRM success and failure, calendar booking failure, authentication timeouts), and safety cases (prompt injection attempts, attempts to extract private data, malicious content hidden in a retrieved document).
Score each test as pass, needs revision, or fail rather than forcing every conversational response into a single number. There is no universal accuracy or conversion threshold that applies to every business, so set your own launch gates based on your risk tolerance and your baseline: every critical happy path passes, no unresolved privacy or security defects remain, every out-of-scope path gets a useful response, every required handoff carries context and actually stops the bot from continuing, and a rollback procedure has been tested and works.
If you're building a retrieval-based bot, a framework for evaluating factual accuracy in an AI system applies directly here: define your test set, your scoring method, and the exact configuration you tested, and never publish a single accuracy number without that context attached.
Common mistake: testing only with the questions your own team wrote. Ask people who weren't involved in building the bot to try realistic tasks, then fold their phrasing and their mistakes back into your test set.
Step 8: Launch gradually and improve from real conversations
Before you open the bot to real traffic, confirm the scope and opening copy are approved, the knowledge sources are current and owned, pricing claims have been reviewed, the privacy notice is live, analytics events are firing, the CRM and handoff routes are staffed, accessibility checks are done, and there's a kill switch if something goes wrong.
Release in stages: internal testing with realistic conversations first, then limited exposure to a controlled audience or a single page, then a review of transcripts and errors before you fix the highest-impact problems and expand to more pages or traffic sources. Add new intents only once the first journey is stable. A chatbot doesn't create value just by existing on a page, so think about where the placement actually meets the audience that needs it: a high-intent landing page, a pricing page, or a page your sales team already refers people to.
Track volume metrics (total conversations, average messages, average duration, since rising numbers here can mean people are struggling rather than succeeding), outcome metrics (completion rate for the intended journey, qualified leads created, handoff rate), and quality metrics (fallback rate, repeated-question rate, integration failures). Define each one precisely; "qualified lead" needs an explicit rule, not a feeling.
Run a weekly loop: review failed and abandoned conversations, group the failures by intent or integration, prioritize by frequency and risk, fix the actual source or flow rather than just lengthening a prompt, add the new examples to your regression set, test the change, and publish with a version note you can point back to later. This is the same discipline behind an editing workflow built to scale: clear owners, defined gates, and a record of what changed and why, so quality doesn't quietly drift as the system grows.
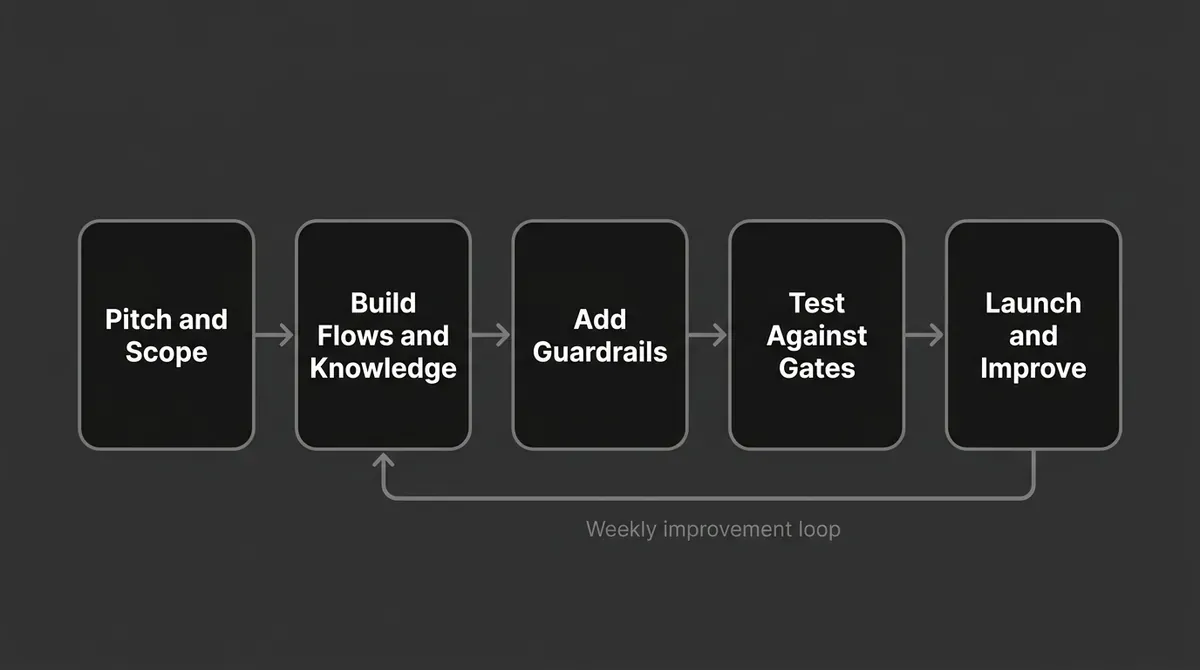
The process is not a straight line: the weekly loop in step eight feeds back into steps three and four, which is why a chatbot needs a fix-and-retest habit, not a single big-bang launch.
Once the chatbot is live, DeepSmith's role picks back up on the marketing side: its AI visibility tracking can show which buyer questions are showing up in AI search and where your brand is or isn't getting cited, and its content production workflow can turn what you learn from chatbot transcripts into the FAQ and use-case content that supports the same journey from the outside. Starting a free trial is a reasonable place to start if you want that surrounding work handled without adding it to your own plate. None of that replaces the chatbot's own logs, its CRM routing, or its human support queue. Those stay yours to run.
What to do next
Start with one customer journey, not five. Build the charter and the test matrix before you touch a builder, and get the human handoff working before you add a single extra feature. The teams that build a chatbot marketing can point to with confidence a year later are almost always the ones that shipped the smallest useful version first, then grew it from real conversations instead of a wish list.


