Your organic traffic just fell off a cliff and the first Slack messages are already landing in your inbox. You don't know the cause yet, and you won't for a while. What you can control right now is how the business responds while that answer is still missing. This guide gives you a first-weeks playbook for a cmo traffic drop response: who owns it, what to tell people, how to size the damage, and how to keep demand moving while the technical team does its work. It is not a technical SEO diagnosis. This is the leadership playbook seo drop moments call for: the operating system that sits around one.
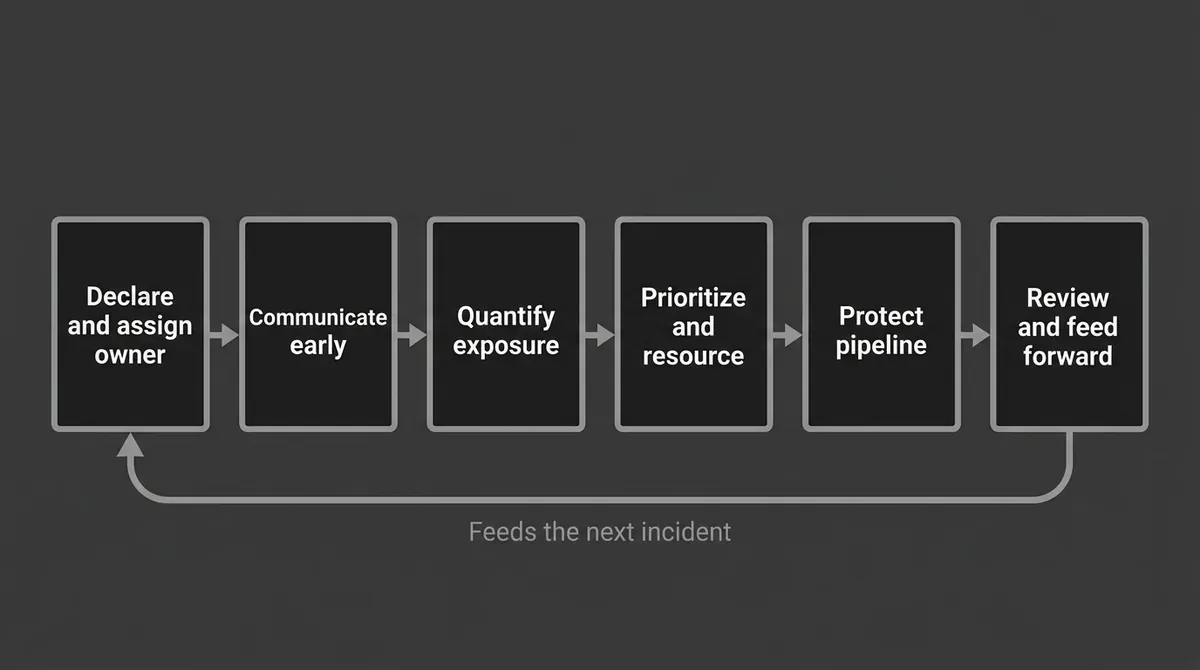
Declare the incident and name one owner
The moment the decline looks material enough to threaten a business outcome (pipeline, a launch, a board number), treat it as an incident, not a bad week. Write a one page brief and put it somewhere everyone on the response can find it. Include the date you first noticed the change, the channel and business areas it touches, the baseline you're comparing against, what you already know, what you don't, the metrics that might be exposed, who owns the response, the first three decisions that need to get made, and when the next update goes out.
Set up one shared place for the response: a channel, a doc, a folder, whatever your team already uses. Keep the action list, the decision log, the scorecard, and every assumption in that one spot so nobody is working from an old version.
You can tell this step is done when one person is clearly accountable, a technical workstream owner is named separately, a communication cadence exists in writing, and the first executive update is already on the calendar. Anyone on the team should be able to tell you who decides, who investigates, who communicates, and when the next check-in happens.
This is usually where a traffic crisis response plan falls apart before it starts. Teams either form a big committee with no one actually empowered to decide, let three different leaders offer three different explanations, or hand the SEO lead the technical investigation, the budget calls, and the executive updates all at once. That's too much for one role and it slows everything down.
Pro tip: call this a performance incident, not a ranking penalty or an algorithm hit, until the evidence says otherwise. Neutral language keeps blame out of the room and keeps the team free to change its read on the situation as new facts come in.
Send the first stakeholder update before you have all the answers
Don't wait for a finished diagnosis to tell people what's going on. Send a short, honest update to the CEO or executive team, finance, sales, product, demand generation, content, and any agency or platform partner who needs to act on this. Use one consistent message across every audience rather than a different story for each room.
Answer eight questions in that first note: what changed, when you first saw it, which business outcomes might be touched, what you know, what you don't know yet, what the team is doing right now, what decisions or support you need, and when the next update is coming. Say that organic demand is down over the period you're measuring. Don't say a named algorithm update, a vendor, or a specific team caused it unless that's actually been confirmed.
A simple template works here. State what was observed and the business relevance you're assessing (pipeline, conversions, forecast). List only confirmed facts under "known." Put the cause, duration, affected segments, and recovery path under "unknown," since those are still open. Name the evidence workstream and demand-protection actions underway under "now," and close with a specific date and owner for the next update.
You'll know this step is done when every stakeholder who needs to act has the same facts, the same open questions, the same named owner, and the same next checkpoint. Finance and sales should know whether the forecast stands as is, is under review, or now carries a scenario range.
The most common failure here is waiting for certainty. Teams stall the update until the investigation wraps, send a traffic chart with no business context attached, or accidentally promise a recovery date they can't keep. An update can be genuinely useful even when the cause is still unknown, as long as it's honest about what is and isn't confirmed.
Turn the traffic decline into business exposure
A chart showing sessions down and to the right is not, by itself, a business case. Replace that conversation with a one page executive scorecard, built on a consistent baseline, where every number is labeled as actual, estimate, assumption, or scenario.
Cover eight areas: the demand signal (clicks or sessions, and over what period), search visibility (impressions, click-through rate, and position trend, not position alone), scope (which pages, products, markets, or content groups are affected), demand type (branded versus non-branded), funnel effect (sign-ups, leads, qualified opportunities, conversion rate), commercial exposure (what pipeline or revenue forecast depends on this demand, and what assumptions back that number), operating exposure (which campaigns, publishing plans, launches, or agency work now need a second look), and confidence (which conclusions are solid, directional, or still exploratory).
Pull search-performance numbers from Search Console and conversion or commercial numbers from your analytics, CRM, and finance systems. Keep the property-level and page-level totals consistent in how you explain them, since aggregation rules can differ between views and that's an easy way to confuse an executive audience.
You're done when you can explain the difference between a traffic decline, a conversion decline, and a revenue-risk estimate on one page, with a baseline, comparison period, affected scope, commercial assumptions, an owner, and a refresh date attached.
The mistake teams make most often is treating sessions as a stand-in for revenue, leading with average position as if it were the outcome that matters, mixing incompatible time periods, or reporting a precise revenue-loss figure that the attribution model genuinely can't support. If you don't have a defensible number, say so and give a range instead.
Rank the recovery backlog and pause what doesn't earn its spot
An incident tends to generate an unlimited list of SEO tasks. Turn it into a short list of decisions instead. Score every proposed piece of work against five things: business impact, confidence in the evidence behind it, time to a useful signal, reversibility, and how much effort and how many dependencies it needs.
Protect anything tied directly to high-intent demand, existing customer commitments, revenue-critical launches, or conversion paths you already know work. Put a hold on low-confidence projects, speculative content ideas, low-priority redesigns, and anything that eats specialist time without a clear decision attached to it. You don't need to stop every content or SEO activity by default. The job is deciding what continues, what pauses, and what changes owner or scope.
This step is done when you have a small, named set of active recovery priorities, each with an owner, an expected signal, a due date, a dependency, and a clear rule for when to stop or continue. Keep a separate list of what you deliberately paused and why, so nobody has to guess later.
Where teams go wrong: they confuse activity with recovery, push out a wave of unrelated content, cancel the SEO program entirely, or let whoever shouts loudest override the work with the clearest business case.
If part of your response also means understanding visibility in AI answers, not just Google organic, a platform like DeepSmith's AI Visibility module gives you that adjacent read. It tracks mention rate, citation rate, share of voice, sentiment, and visibility trend across the AI engines it covers, with competitor and page-level citation views, so you can see whether the problem is limited to traditional search or part of a wider discoverability shift. That's a separate signal from a Google ranking diagnosis, not a fix for one, and it should be treated that way.

Build three scenarios and reallocate spend on purpose
Instead of committing to one confident forecast, build three planning views. A base case, where the decline stabilizes and the existing plan continues with some adjustments. A downside case, where the decline persists or spreads to more commercial segments. A recovery case, where leading indicators improve and you can scale up the investments that are working.
For each scenario, write down the trigger conditions, the expected business exposure, the budget changes, the people and specialist capacity involved, the channel alternatives on the table, which decisions can be made now, which need more evidence first, and the date for the next review.
Review spending by channel, media type, segment, geography, agency, and program. Look for inefficient or overlapping work to reallocate rather than cutting everything by the same percentage. Where your team already has the skill in house, bringing work back in can improve speed and control. Where the capability is genuinely missing, name the specific outside support you need rather than defaulting to outsourcing the whole response.
A small cross-functional group works best here: one coordinator, plus representatives from analytics, channel operations, creative or content, finance, and legal or compliance if the situation calls for it.
You'll know this is working when you can show, on one page, what's protected, what's paused, what's newly funded, what assumptions drive each of those calls, and what would need to change for the plan to change. Finance should be able to trace every major resource decision back to a scenario or a stated business objective.
The common trap is making blanket cuts before you understand the actual exposure, protecting every existing program purely because it's familiar, or moving money into a new channel without setting measurement rules and a stop condition up front.
Protect pipeline while search stays unstable
Build a temporary demand-protection plan that reduces how much you're leaning on one acquisition channel while organic search is unsettled. Consider lifecycle and email activation of audiences you already have, sales enablement for high-intent accounts and open opportunities already in motion, narrowly targeted paid coverage where the unit economics still make sense, partner, community, and referral distribution, repurposing strong existing content into channel-native formats, direct outreach to segments showing active buying signals, and conversion or retention work on demand you've already earned.
These are options to select from, not a checklist to run in full. Pick the channels that fit your business, that you can actually measure, and that you can staff. Treat any paid replacement traffic as an experiment with an explicit cost, quality, conversion, and stop rule attached, not as an automatic substitute for organic demand, since the economics and lead quality are usually different.
Align sales, customer success, product marketing, and communications on one shared explanation. If a prospect asks about the drop or a product change, every team should be working from the same answer instead of improvising one on the spot.
You're done here when there's a written channel coverage plan, an owner for each demand-protection action, a measurement method attached to each one, and a date set for deciding whether to scale, adjust, or stop it.
Watch for teams that buy broad traffic just to make the top-line chart look better, ignore whether the leads that traffic brings are any good, overload sales with unqualified volume, or treat this as a one-time campaign instead of an ongoing operating response for as long as the incident lasts.
Run a weekly evidence-based recovery loop
Set a short, deliberate operating cadence rather than an open-ended set of standing meetings. Review material changes, blockers, and decisions daily for the first week. Refresh the executive scorecard and assumptions twice a week while the exposure is still uncertain. Hold a weekly decision meeting with the CMO, the response coordinator, analytics, finance or RevOps, content, demand generation, and sales. At every one of those meetings, close out completed work, drop stale tasks, record the decisions made, update scenario status, and name the next piece of evidence you need.
Track leading and lagging indicators separately. Leading indicators can include impressions, qualified visits, branded demand, engagement from target accounts, channel response, and content production progress. Lagging indicators are qualified leads, opportunities, pipeline, revenue, retention, and margin. Use a simple decision log with four statuses, continue, change, pause, and stop, and don't let the team treat every daily wobble in the numbers as a verdict on the whole plan.
For teams that need an ongoing view of AI-search visibility during this stretch, DeepSmith can track your prompts on a schedule, capture the answers, and separate a plain brand mention from an actual citation to your pages, with competitor views showing which pages are winning citations and what competitors are publishing. DeepSmith's Content Studio can also carry an approved content backlog through research, writing, linking, metadata, and imagery to a publish-ready draft grounded in your stored brand context, with Planned Content and Autowrite handling the scheduled production and Produced Content keeping a human in the review and publish step. The Apps Library can turn an approved piece into LinkedIn, X, newsletter, and other channel-native assets once it's live.
Worth saying plainly: DeepSmith helps you measure AI visibility and run content production at pace. It does not diagnose a Google ranking decline, guarantee recovery, or replace the technical SEO work and business judgment this incident actually needs.
You know this loop is working when every week ends with a clear status on each action, an updated scorecard, a documented decision, and a next checkpoint, and when you can tell whether the response is generating evidence, protecting demand, or just burning hours without a useful signal.
The failure mode to watch for is status meetings that produce no decisions, changing several variables at once so you can't tell what actually moved the number, forgetting to write down the assumptions behind a call, or mistaking busy activity for real recovery.
Close the incident and write the postmortem
End incident mode because you've hit explicit exit conditions, not because one good day showed up on the dashboard. Reasonable exit conditions: the affected metric has stabilized against your agreed baseline, the scorecard shows a reliable trend rather than one good data point, temporary demand-protection work has been scaled up, wound down, or folded into normal planning, budget and staffing decisions are documented, remaining open risks have owners and dates, and stakeholders agree on what uncertainty is still left and how you'll operate with it.
Once you close it, run a blameless review. Record the timeline, the signals you saw, the decisions made, the assumptions behind them, how well the communication worked, the resource choices, channel performance, and whatever questions are still unresolved. Update your crisis plan, your alert thresholds, your stakeholder list, your dashboards, and your ownership map while the experience is still fresh, not months later when the details have faded.
This step is done when you have a written closeout, a normal operating owner for anything left over, and a specific resilience backlog to work through next.
Teams go wrong here by closing the incident too early after a short rebound, never actually removing the emergency-mode work once it's no longer needed, or running the postmortem as a blame exercise that just teaches people to hide uncertainty next time.
What to do next
A marketing leadership seo decline response works best when it becomes a standing part of how the business operates, not a one-time fire drill. Turn what you just ran through into that standing system. Define your own alert threshold and the metric that trips it before the next decline arrives. Name a cross-functional owner in advance. Keep the executive scorecard format on hand so it's ready the moment you need it. Diversify your demand channels so no single one carries the whole business. And keep a maintained response plan on file so the next organic traffic tanked moment starts from a plan instead of a blank page.
If part of that standing system includes knowing where your brand shows up in AI answers and keeping your content pipeline moving without adding headcount, DeepSmith's AI Visibility and Content Studio are worth a look. You can start a 7-day free trial and see your own data before you commit to anything.