A blog archive by itself does not tell you much. You can scroll through a competitor's posts for an hour and walk away with a feeling, not a picture. This guide gives you a repeatable way to analyze competitor content strategy and turn that archive into an actual map: what topics a competitor keeps coming back to, how often they publish something genuinely new, which formats they favor, and what that pattern can honestly tell you about where they're putting their effort. By the end you'll have a one-competitor operation map you can hand to someone else and they could reproduce it.
To reverse engineer competitor content, you build a dated inventory of its public pages, sort them into topics and formats, count new pages separately from updates to old ones, then look at which subjects get sustained coverage, distribution, and citations. What you end up with is an evidence-labeled picture of what the competitor publishes, how regularly, and what their visible activity suggests about their priorities. Their staffing, budget, and internal motives stay guesses unless they say so publicly.
This is a picture of one competitor's operation, and that's the whole job here. It won't hand you a ranked list of your own content gaps (that's a separate exercise) and it won't walk you through keyword-level analysis. Keep it to this one thing and it'll actually be useful.
Set the competitor and the observation window
Pick one competitor that serves a buyer or use case close to yours. Write down their main domain, any subdomains that matter, the channels they publish on, and which asset types you're including. A good rule of thumb is a recent 90-day window to read current cadence, plus a trailing 12-month window to catch seasonality and topics they maintain over the long run. Decide up front whether product pages, docs, news, job listings, syndicated pieces, and event pages count, and note which of those are owned by the competitor versus just mentions of them elsewhere.
You're done with this step when someone else could take your notes and reproduce the same scope, window, and inclusion rules without asking you anything. Your working sheet should have an analysis date on it and a plain definition of what counts as one asset.
Where this goes wrong: people pick a famous rival whose business model doesn't actually match theirs, or they count changelog entries and translated copies of the same article as if each were a new piece. The 90-day and 12-month windows are choices you're making for this analysis, not a claim that every company publishes on that schedule.
Build a public URL inventory
Start at the competitor's visible blog or resource index, then find their public sitemap or sitemap index. Follow the links into blog, resource, documentation, and case-study sections, and check for an RSS or Atom feed if they offer one. Keep in mind that a sitemap gives you candidate URLs, not a complete or editorially curated list. For every distinct page that's in scope, keep a row with its URL, title, section, apparent format, observed date, and where you found it. Flag redirects, dead pages, duplicates, translations, and syndicated copies instead of quietly folding them into your totals. An archive snapshot can help you settle a dispute about an older version of a page, but a capture date is not a publication-date certificate. Use it to break ties, not to declare a scoop.
You're done when the inventory covers the relevant sections, the URLs are deduplicated, and your exclusions are written down somewhere. Spot-check by actually opening pages rather than trusting the sitemap listing as gospel.
Where this goes wrong: treating a sitemap's entry count as the whole content operation, assuming a page being in the sitemap means Google indexed it, or missing content the competitor publishes off their main blog. Google itself says sitemaps help with discovery but don't guarantee crawling or indexing. Treat the sitemap as a starting point, not a verdict.
DeepSmith's Content Map crawls your site and your competitors' sites into a shared topic taxonomy, which is a fast way to keep a running map instead of rebuilding this inventory by hand every time. It's still worth checking the scope and classification it produces for the specific competitor you're profiling. It won't show you a competitor's private content or every asset they host somewhere obscure.

Classify the subjects they keep covering
Give each URL one primary topic based on the central question the page answers, not just a word that happens to be in the title. Add a secondary topic only when the page genuinely covers a second subject in depth. If it's useful, note a buyer-stage read too: awareness content educates on a problem, consideration content compares approaches, decision content covers implementation, proof, pricing, or vendor evaluation. Set aside anything ambiguous for a second look. For each topic, summarize how many distinct pages sit under it, the mix of stages and formats, and how recent the coverage is. Actually read the representative pages before you call a cluster deep. Five near-identical posts on the same angle are different evidence than one guide, one comparison, one case study, and one documentation page that each serve a different reader need.
You're done when you can name the subjects a competitor returns to and point at the pages behind each one. A second person looking at your notes should understand why each representative page landed where it did.
Where this goes wrong: counting synonyms as separate topics, reading a URL slug as if it were the substance of the page, calling something a strategic priority off one article, or treating an automatic label as if it proved editorial intent.
Content Map classifies pages onto topics and funnel stages, and maps competitor sites onto a shared taxonomy so you can compare concentration and breadth across sites. Use it to get the first pass, then check anything ambiguous or unusually important by hand. It does have coverage-gap views built in, but that's a different exercise from the one-competitor portrait you're building here.
Separate when they launch from when they maintain
For each asset in scope, look for a clearly labeled publish date on the page itself. Check for a separately labeled last-updated date or structured data if it's there. If dates conflict, use feed entries, older captures, or the page's edit history to sort it out. Build two separate series: new distinct pages by month, and existing pages that got a substantive update by month, with unknown dates kept in their own bucket. Report the actual monthly counts and their spread for a recent period, not just an average, and only call out a burst or a repeated day-of-week pattern if your dated sample actually supports it. If you're comparing two periods, hold the page types and date rule constant across both.
You're done when your timeline clearly marks which rows are new, which are updates, which dates you're unsure about, and what share of the inventory has reliable dates at all. An honest finding here can be that cadence simply can't be established from the public dates you have.
Common mistake: seeing thirty URLs with new sitemap timestamps this month and concluding the competitor published thirty articles. Those timestamps might just be edits to existing pages. Verify the actual page-level publication date and count new URLs on their own.
Where this goes wrong beyond that: reading a sitemap's lastmod field as a publish date, counting a refreshed post as new output, treating a search-result date or a first archive capture as solid publication evidence, or announcing a precise weekly cadence off a short, patchy archive. Google recommends visible, clearly labeled dates and supports separate published and modified fields in article markup. A visible, well-labeled date beats a guess every time.
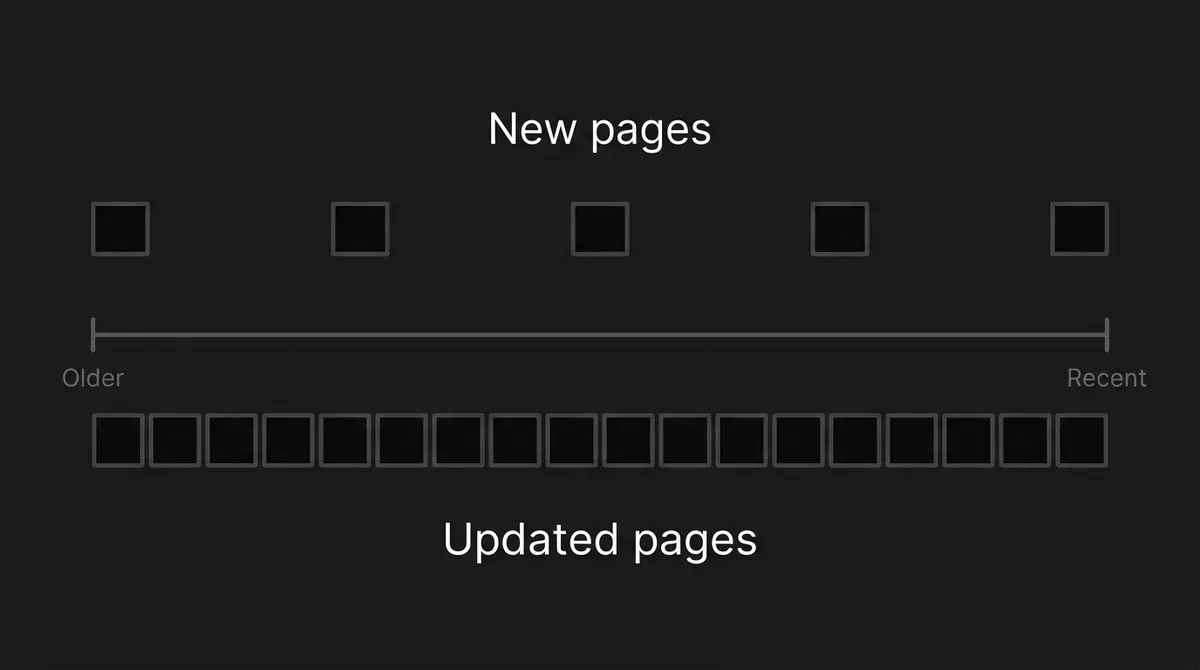
DeepSmith monitors competitor sitemaps daily and folds newly discovered pages into Content Map automatically, which helps you notice new public URLs without checking manually. It won't tell you the original publish date of every page, the full size of a competitor's output, or whether a changed sitemap entry actually represents a new article. You still need the page-level check above.
Count the formats and where they distribute
Assign each asset one primary format, and separately note obvious supporting assets around it. Work from what the page actually is: an actionable how-to, an opinion or thought-leadership piece, a comparison, a research or data report, a case study, a template, a webinar or video, a documentation page, a product page, and so on. Count the mix across the whole inventory and again just for the recent window. Look closely at representative assets for depth and production effort: original interviews, charts, interactive elements, downloadable files, screenshots, video, a named author, update notes. Check the competitor's visible newsletter, video channel, and social accounts to see if the same article gets repurposed there. Only record distribution you can actually observe. A newsletter signup form on the site doesn't tell you a given post went out in an email.
You're done when you can name the formats they favor, with counts or shares from a defined sample, and point to actual examples. Your notes should distinguish an original asset from channel-specific promotion of that asset.
Where this goes wrong: assigning a format from the title alone, calling an embedded video an independent video campaign, treating one social post as evidence of a distribution strategy, or comparing a documentation-heavy company against a blog-only one without separating the channels first.
Read for substance and visible signals of emphasis
Read representative assets from the biggest, newest, and most distinct topic clusters. Note the audience they're writing for, the editorial angle, what kind of evidence they use, who they cite, whether the author has visible expertise, the calls to action, the links to related pages, and whether the piece connects to a specific product capability. Look for repeated series, foundational pages that get kept up to date, and multiple formats all serving the same subject. If you're also checking AI-search exposure, use a fixed set of buyer questions and record the engine, date, the full answer, which brands got named, and which pages got cited for each one. A page that keeps showing up as a cited source is a real signal within that specific question set, not proof of overall content quality or a claim about their traffic.
You're done when every priority you propose has examples and at least two kinds of support where possible, such as repeated pages plus a recent publish date, or a maintained guide plus supporting documentation. Any AI-search findings should state the question set and the window you checked it over.
Where this goes wrong: treating a citation as an endorsement, a mention as if it were a link, or one sampled AI answer as permanent visibility. Google has said AI Overviews and AI Mode can show different responses to different people, and an outside analyst doesn't get access to a competitor's private Search Console data just because an answer got sampled once.
AI Visibility tracks the prompts you define and separates mentions from citations, and its competitor view shows which specific competitor pages got cited for those prompts, broken down by engine. Define your questions first and describe the results as observations over tracked prompts, not a complete picture. It won't hand you a competitor's conversion numbers or catch every possible AI answer that exists, and which engines you can track depends on your plan.
Infer priorities and resourcing without pretending to inside knowledge
Build a small table: evidence on one side, inference on the other. For each priority you're proposing, list the pages, formats, dates, maintenance pattern, distribution, and any repeated AI citations behind it. Then write a bounded inference with a confidence level and a plausible alternative explanation. A sustained run of distinct implementation guides plus documentation that gets kept current suggests an emphasis on enablement. It doesn't prove a specific headcount or revenue target sits behind it. A polished quarterly report might reflect an internal research team, outside contributors, or an agency, and you can't tell which from the outside. Author bylines, job postings, and public announcements can add useful context, but don't turn them into a hard count of the content team.
You're done when your summary clearly separates what you observed, what you're inferring, and what's genuinely unknown, and explains why the inference is reasonable and what evidence would change your mind. This table is the step that actually lets you analyze competitor content strategy instead of just describing a pile of pages.
Pro tip: if you can't tell you're guessing, write the inference down as a sentence starting with "this suggests" or "this may reflect" rather than a flat statement. It keeps you honest and makes the finding easy to challenge later.
Where this goes wrong: back-solving a headcount from article volume, inventing a cost per post, assuming a recent burst of activity is permanent, reading a gap in an incomplete sitemap as proof a subject got abandoned, or assigning a competitor a motive they never stated.
Produce a one-competitor operation map
Pull it together into one profile: the scope and its limits, total countable assets and recent new-page counts, the leading topic clusters with representative URLs on your working sheet, the format and funnel-stage mix, the new-versus-refreshed cadence, what distribution you actually observed, your evidence-labeled priority and resourcing hypotheses, and the open questions you couldn't resolve. Put the observation date and a short method note on it so the whole thing could be repeated by someone else.
You're done when a marketing lead reading it can answer four questions about that one rival: which subjects get sustained attention, how often distinct new assets show up, which formats recur, and what can and can't be said about their investment and editorial priorities.
Where this goes wrong: closing the map with an unsourced prescription for your own backlog. Deciding what you should write next is a separate exercise from mapping what a competitor already did.
What to do with the map
That's deliberately not part of this guide. Once you have the operation map, the natural next step is a separate gap analysis against your own content: where you already compete on a topic, where you have nothing, and where the format mix suggests an opening. DeepSmith's Content Map and AI Visibility modules can carry the inventory, classification, and tracked-prompt citation checks described above so the manual parts of this process take less of your afternoon, and you can start a 7-day free trial to see your own map take shape against a competitor you already have in mind.